How Does a CIO Make an AI Rollout Succeed?

Many companies are moving money toward AI, not away from it. Budget is not normally the main obstacle. The problem a CIO owns is making that rollout successful. A first AI rollout that stalls, gives wrong answers, or quietly underdelivers does not just miss this quarter's numbers. It burns the trust that would have funded the next one. A board or functional leader who watched one AI investment disappoint is a much harder audience the second time.
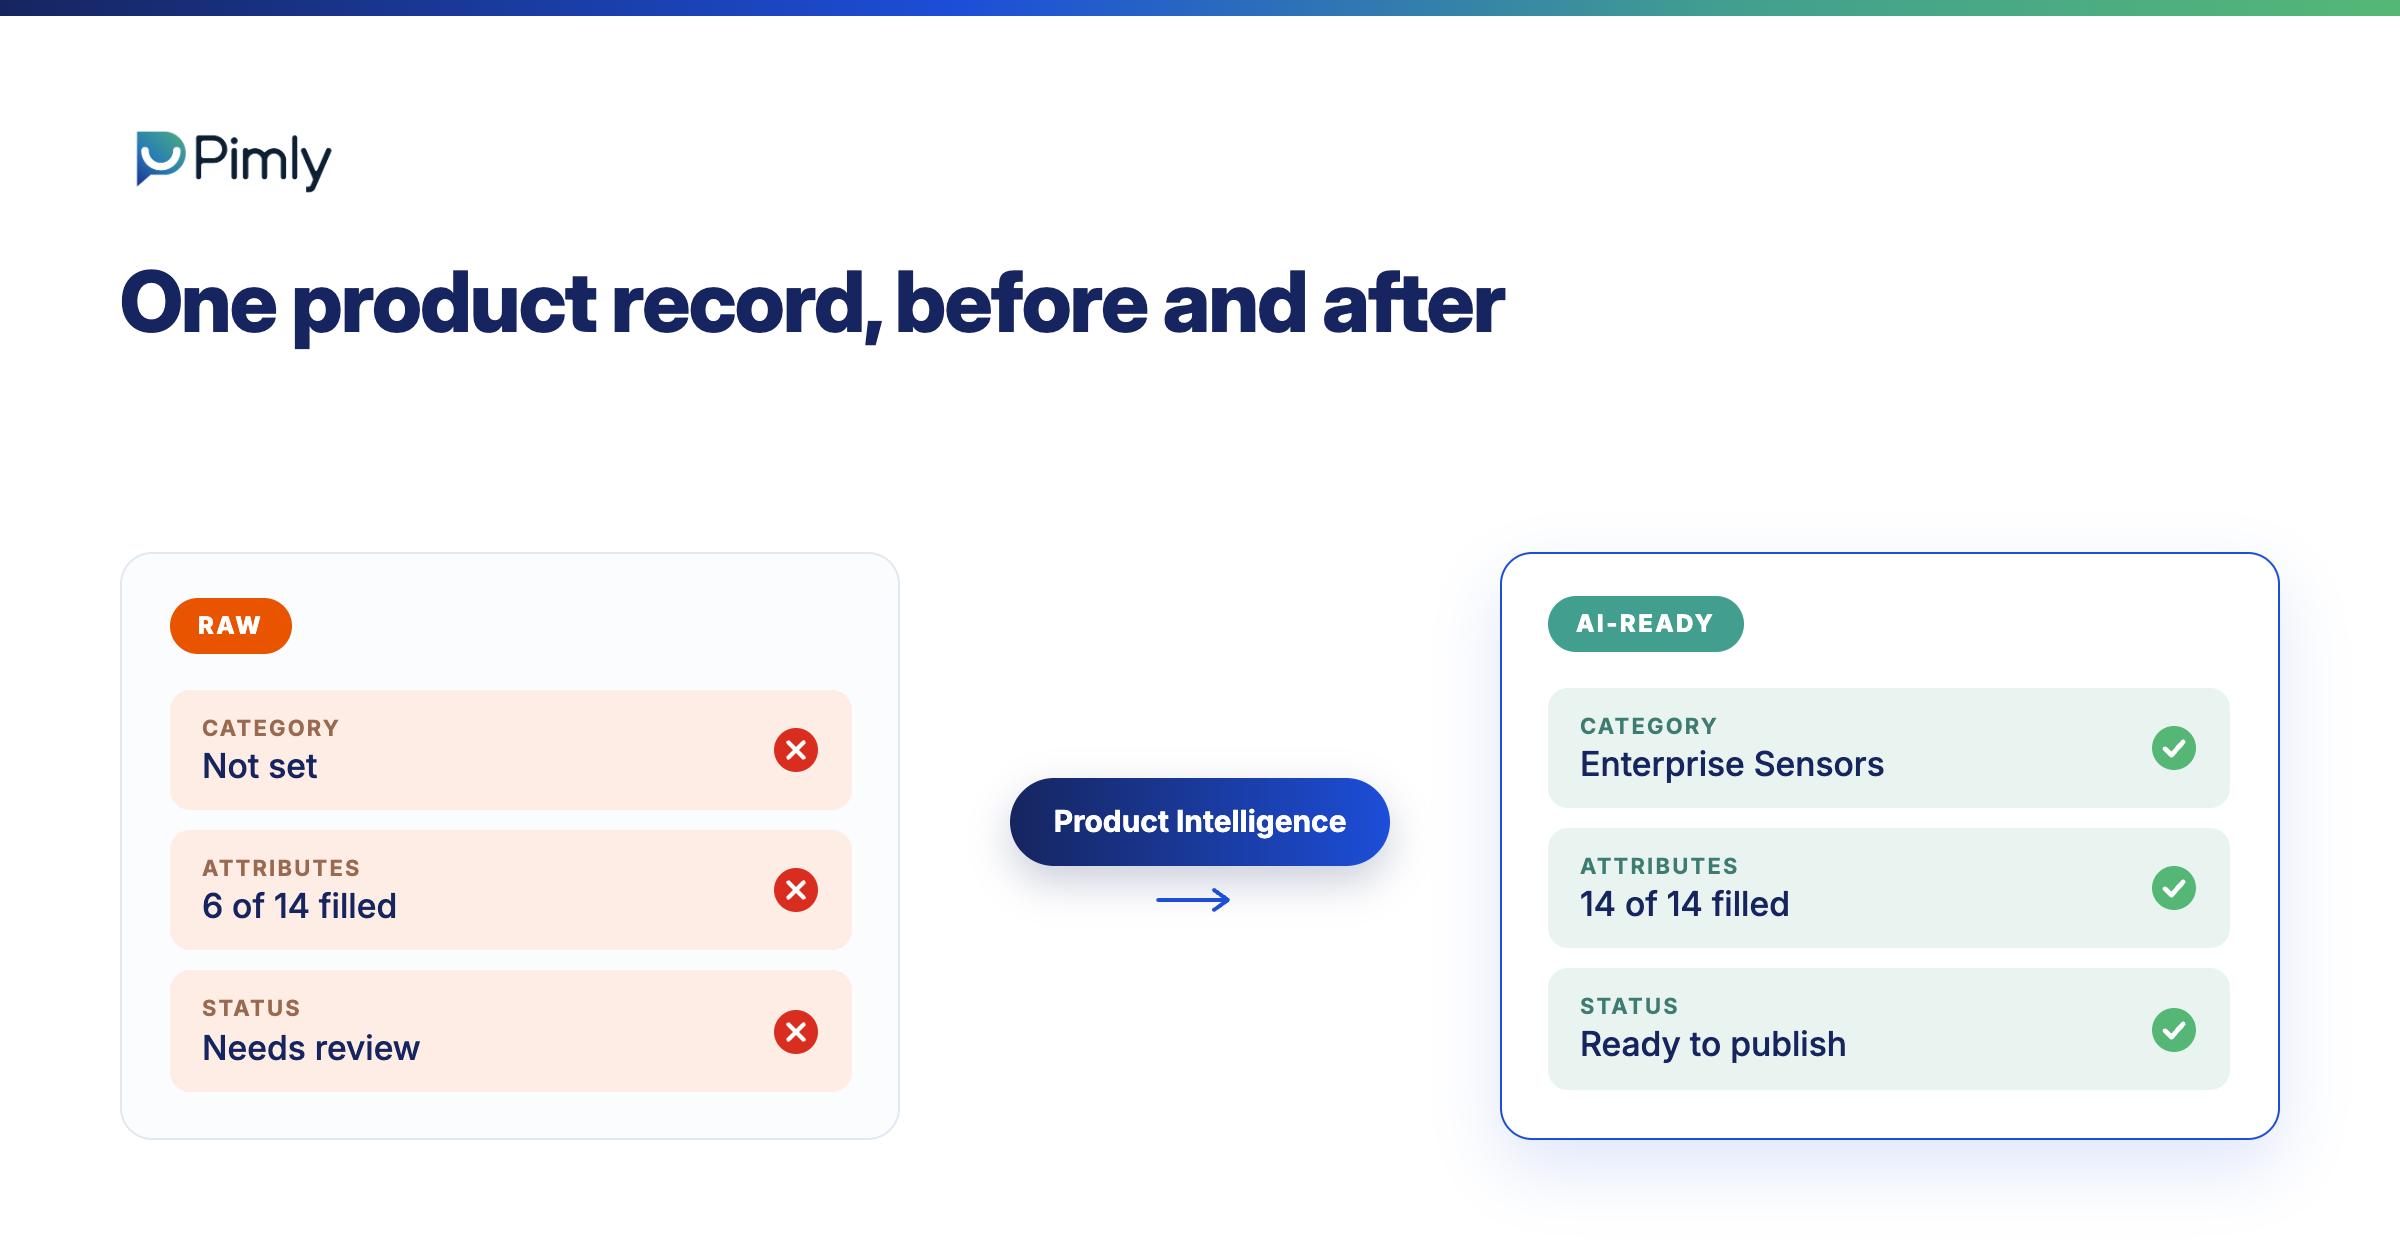
Making that first rollout succeed comes down to a sequencing decision many CIOs don't prioritize. AI-ready product data means accurate, complete, structured, and well-governed enough for AI to use without human intervention. It is not a compliance checkbox. It is the condition an agent needs before it can answer a product question correctly instead of confidently guessing. Every functional leader in the business gains something different once that foundation exists.
Skip straight to the board with the data problem still unsolved, and the rollout inevitably disappoints. Reps stop trusting the AI agent's answers and go back to calling engineering. Service agents escalate cases they should be able to close on their own. Marketplace listings stay incomplete. Six months in, the board starts asking why the AI investment isn't showing up in the numbers it was funded to move. None of that is an AI problem. It is a data and sequencing problem, and it is exactly the kind of stall that makes the next AI initiative a harder sell.
This is written for the CIO, COO, or VP of Digital responsible for making this AI rollout succeed. It covers how to build the case with the leaders who run sales, service, eCommerce, and marketing first, and how to turn that alignment into a case the CFO and the board will approve now, and celebrate in 6 months when the rollout exceeds expectations.
Key takeaways
- AI budget is not the hard part. Making the first AI rollout succeed is. Every rep and every AI agent becomes a product expert once the data underneath them is fixed, so sales quotes faster and cross-sells more, service resolves cases without escalating, and eCommerce and marketing channels carry complete, accurate product content.
- The case to peer leadership and the case to the board are different arguments, not the same pitch said twice. Peers need to see what changes in their own numbers. The board needs risk, cost, and payback.
- Fixing product data is not a competing initiative or a separate budget ask. It belongs inside the same AI rollout budget as one line item, not two, which is what enables a CFO to validate the model instead of treating it as scope creep.
- GE Vernova's fivefold cross sell lift after unifying roughly 200,000 SKUs is evidence that fixing data changes revenue outcomes, not just data quality scores.
Try our Free Product Data Grader before your first leadership conversation. It takes about a minute and gives you a concrete starting point for the case you are about to make.
Why do AI rollouts stall even when the budget is approved?
The budget for an AI initiative just got approved, and everyone on the leadership team and the board is looking at the CIO for one thing: speed. The CIO already knows there's a data problem underneath, but the pressure from above isn't "fix this properly." It's "show us this is live." Surfacing the data problem now feels like it could blow up the timeline, or the budget, or both, on an initiative everyone just signed off on and wants to see moving. So the CIO does what the organization is asking for by rolling out AI on top of the data as it already exists. That's the decision that normally guarantees the stall. It doesn't show up on day one. It starts to show up a few months in when reps stop trusting the answers and service agents keep escalating cases. And then it really shows up at the next board meeting when the numbers haven't moved.
What does each leader gain when product data comes first?
Sales: faster, more accurate quoting and confident up-sell and cross-sell
A sales VP does not care that a product record is governed. They care that reps quote the right configuration the first time and stop losing deals to slow or inaccurate quotes. When product data is accurate and complete inside Agentforce Revenue Management (ARM), reps and AI agents generate quotes against real compatibility and bundle data instead of guessing from a spec sheet someone emailed last quarter.
Cognex is rolling out AI-powered quoting to 1,500 sales reps this way, so every one of those reps can ask a natural-language question across thousands of pages of technical specs and get back an accurate quote on a complex, configurable product, because the data underneath was fixed first. That is the number a sales leader remembers. Not data quality, but 1,500 reps who stop escalating configuration questions to engineering, the same shift documented in how a sales rep becomes a product expert on technical SKUs.
Service: case resolution without the escalation
A service leader's real measure is resolution time and first contact resolution, not data completeness. When product and compatibility data lives in one governed place instead of split across a PDF, a spreadsheet, and someone's institutional memory, AI and human service agents resolve cases instead of escalating them. Companies that fix this see customer issue resolution get up to 75% faster once agents stop needing a phone call to figure out the right answer. Every case an AI agent closes correctly on the first try is one that never reaches a human escalation queue.
eCommerce and marketplaces: complete data, fewer returns, no channel gaps
An eCommerce leader is measured on conversion and return rate, and incomplete product listings hurt both. A shopper who cannot confirm compatibility or specs either abandons the cart or orders the wrong thing and sends it back. GE Vernova runs roughly half its business through a B2B Commerce platform built on the same governed catalog, which is exactly the point: one accurate record feeds every storefront and marketplace instead of a separate, thinner export for each channel. We even use the same SmartSync technology to ship your governed, structured product catalog to Shopify, so an eCommerce leader running Pimly for eCommerce alongside a Shopify storefront gets the same benefit without a second data project.
Marketing: consistent content, faster launches
A marketing leader's real constraint is usually speed. Chasing the right spec from ops before a launch, then doing it again once the spec changes. CORT Furniture saw product launches move 1,400% faster once product content did not have to be manually rebuilt for every campaign and channel. That is not a marketing specific feature. It is what happens when marketing teams pull from the same governed record everyone else does, instead of maintaining its own parallel copy that drifts out of date.
See what AI ready product data looks like inside your own product catalog. Book a demo with the functional leaders who would need to sign off.
How does a CIO turn that alignment into a case the CFO and board will approve?
Once sales, service, eCommerce, and marketing leaders are aligned behind an AI initiative that includes fixing the data as the means to achieve their own functional outcomes, the board conversation changes shape entirely. The board is not evaluating whether product data matters. That part is settled. The board is evaluating capital: what this costs, what it risks if skipped, and how fast it pays back.
Why the CFO has to see one budget, not two
The CFO enters this conversation with a different question than the board's. A board asks whether the investment pays back. A CFO asks where the margin is leaking today and whether the model underneath the numbers can be trusted. Mispriced quotes and wrong configurations show up as margin leakage that never gets traced back to the product record that caused it. Returns from a wrong spec or a missing compatibility field cost money that rarely gets attributed to the data problem behind it. Forecast accuracy suffers the same way, because a revenue model built on incomplete product data is only ever as reliable as the record feeding it.
That is why fixing product data cannot be a second budget request submitted after the AI rollout is already approved. If it shows up later as its own line item, the CFO reasonably treats it as scope creep, a cost the original business case did not account for. The CIO has to bring the CFO in early enough to fold the two together: one AI rollout budget that already includes the cost of making the data AI ready. Once the CFO sees it that way, validating the model becomes straightforward, because the inputs to that model are the same governed data feeding the rest of the case.
What the board is weighing
A board does not need the functional detail from the section above. It needs three numbers. First, the cost of the AI rollout succeeding versus stalling. An AI initiative that ships on top of bad data does not just underperform, it actively erodes trust in the platform the company already approved spending on. Second, the payback timeline. W.S. Darley & Co reached full payback on its governed product data foundation in nine months, after evaluating other options and choosing the one that got it live fastest. Third, whether this is a new, competing line item or a sequencing decision inside a budget the board already approved. It is the latter. Fixing product data is not a second initiative asking for its own signature. It is the first phase of the AI rollout the board is encouraging the organization to execute.
The proof that shortens the conversation
Boards move faster when the numbers come from someone else's balance sheet first. GE Vernova's fivefold cross sell lift and Cognex's early adoption of Product Intelligence, where Diana Ferreira, Cognex's Director of IT, has spoken publicly about centralizing product data ahead of expecting faster resolution and more consistent selling, are both the kind of proof a board weighs. A peer company, in a comparable position, that made the same sequencing call. If you need to build the specific dollar figures for your own board deck rather than borrow someone else's, our PIM ROI framework walks through the five step calculation: define the pain points, map the workflows, identify the cost and revenue drivers, build the comparison table, and validate the assumptions once it is live.
Getting the sequencing right
The CIOs whose AI rollout succeeds, instead of quietly stalling six months in, are not the ones with the best AI vendor. They are the ones who fixed the data challenge before or in concert with the AI rollout. Peer leadership signs off because the case is made in their own numbers: sales quotes faster and cross sells more, service resolves cases without escalating, eCommerce and marketing carry complete data across every channel. The board signs off because the ask is framed as cost, risk, and payback, not as a leap of faith. The result: every rep and every AI agent becomes a product expert, answering confidently, quoting accurately, and winning more deals.
Would you like Pimly to help you build the board ready version of this case? Try the free grader first to get the starting numbers, then let's talk.
Frequently asked questions
What is a business case for AI ready product data?
A business case for AI ready product data is the argument a CIO makes to fund fixing a company's product data, making it accurate, complete, structured, and governed, as the first step inside an AI rollout rather than a separate initiative competing with it. It has two parts: the case to peer functional leaders such as sales, service, eCommerce, and marketing, who need to see what changes in their own numbers, and the case to the CFO and board, which needs cost, risk, and payback. Both parts use the same underlying proof, framed for what each audience actually evaluates.
What makes product data AI-ready in the first place?
Product data is AI-ready when it is accurate, complete, structured, and governed enough for an AI agent to act on without a human correcting the output afterward. Accuracy and completeness mean every field a rep or agent needs is actually filled in and correct, not partially populated or years out of date. Structure and governance mean the data lives in one place with clear ownership, rather than fragmented across spreadsheets, PDFs, and someone's inbox.
How is building leadership buy-in different from making the case to the board?
Peer leadership buy-in is an operational argument. It has to show sales, service, eCommerce and marketing leaders what changes in the specific number they are personally accountable for. The CFO and board case is a capital allocation argument. It has to show cost, payback timeline, and the risk of an AI investment underperforming if the data underneath it stays broken. The same evidence supports both, but the board does not need the functional detail, and peer leaders do not care about payback timelines. Each audience needs its own version of the argument.
Isn't getting the AI budget approved the hard part?
Not anymore. Most companies are already moving budget toward AI, so approval by itself is rarely the obstacle a CIO has to clear. The harder problem is making that first rollout succeed, because a rollout that stalls or gives wrong answers does not just underperform, it burns the trust that would have funded the next one. Naming product data as the explicit first phase, with functional and financial proof attached, is what keeps that first rollout from becoming the reason the second one is a harder sell.
How does a PIM help a CIO build this case?
A Salesforce native PIM gives a CIO the governed, structured product data foundation the whole case depends on, without adding a separate system or integration project outside Salesforce. It is also where the proof comes from. Customers like GE Vernova, W.S. Darley & Co, Cognex Corp and CORT Furniture all fixed their product data first and can point to a specific number, whether that is cross sell lift, payback timeline, AI-assisted quoting output or new product launch speed, that a CIO can borrow when making either version of the case.
Should fixing product data be its own budget request, separate from the AI rollout?
No. Product data work should sit inside the same AI rollout budget as a single line item, not as a second request submitted afterward. When it arrives separately, a CFO reasonably reads it as scope creep on a business case that already got approved. When a CIO folds it in from the start, the CFO can validate the underlying model instead of relitigating the budget, and the board never has to reconcile two asks that were always one.